Symphony for Speech-to-Text
The most accurate speech-to-text models
Symphony for Speech-to-Text is clinical speech recognition for healthcare developers. Real-time medical dictation, ambient documentation, and batch audio, with structured transcripts via REST and WebSocket.
98.6%
Word accuracy. 1.4% Word Error Rate in English realtime
#1
Medical dictation benchmarks in English, French, and German
98.5%
Formatted entity recall on dosages, units, measurements
50%
Fewer missed terms with keyterm biasing
Trusted for more than 1 million interactions every week
Symphony for speech-to-text
Clinical speech recognition API
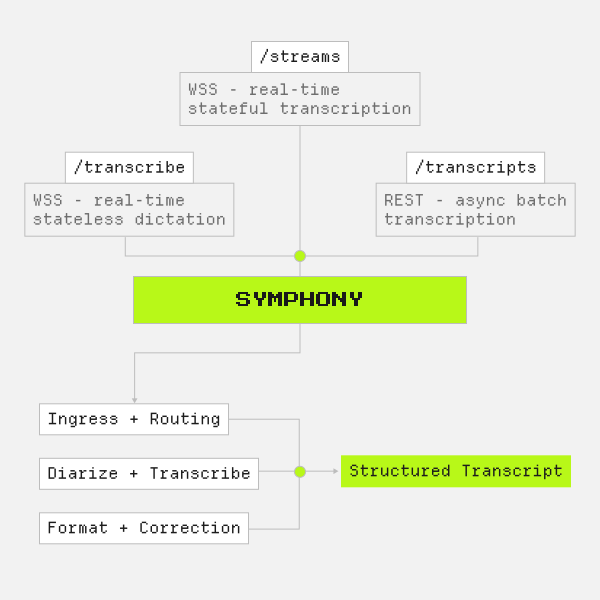
Three endpoints supporting every clinical audio workflow. All three run through the same underlying pipeline: medical recognition, structured formatting, and contextual correction.

Real-time stateless dictation
/transcribeis for low-latency WebSocket streaming dictation, with command and control for voice-enabled apps.
Real-time ambient documentation
/streamsis for stateful WebSocket transcription of clinical conversations, with diarization and multichannel audio.
Asynchronous batch transcription
/transcriptsis a REST endpoint for transcribing pre-recorded audio files, with diarization and async processing.
An orchestrated pipeline, not a single-pass model
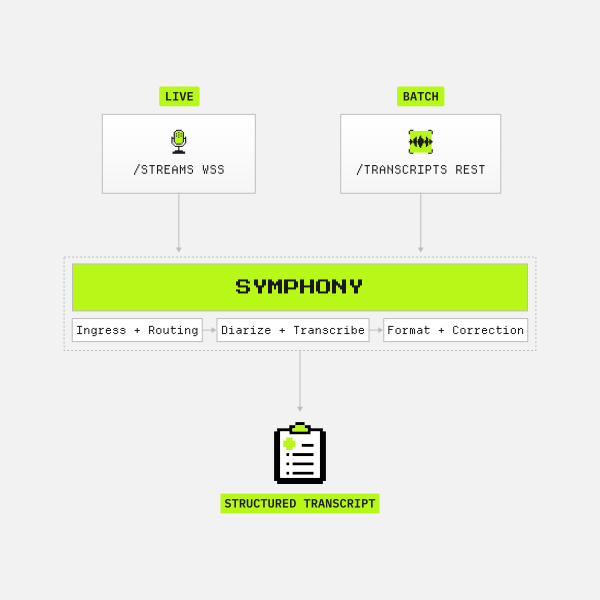
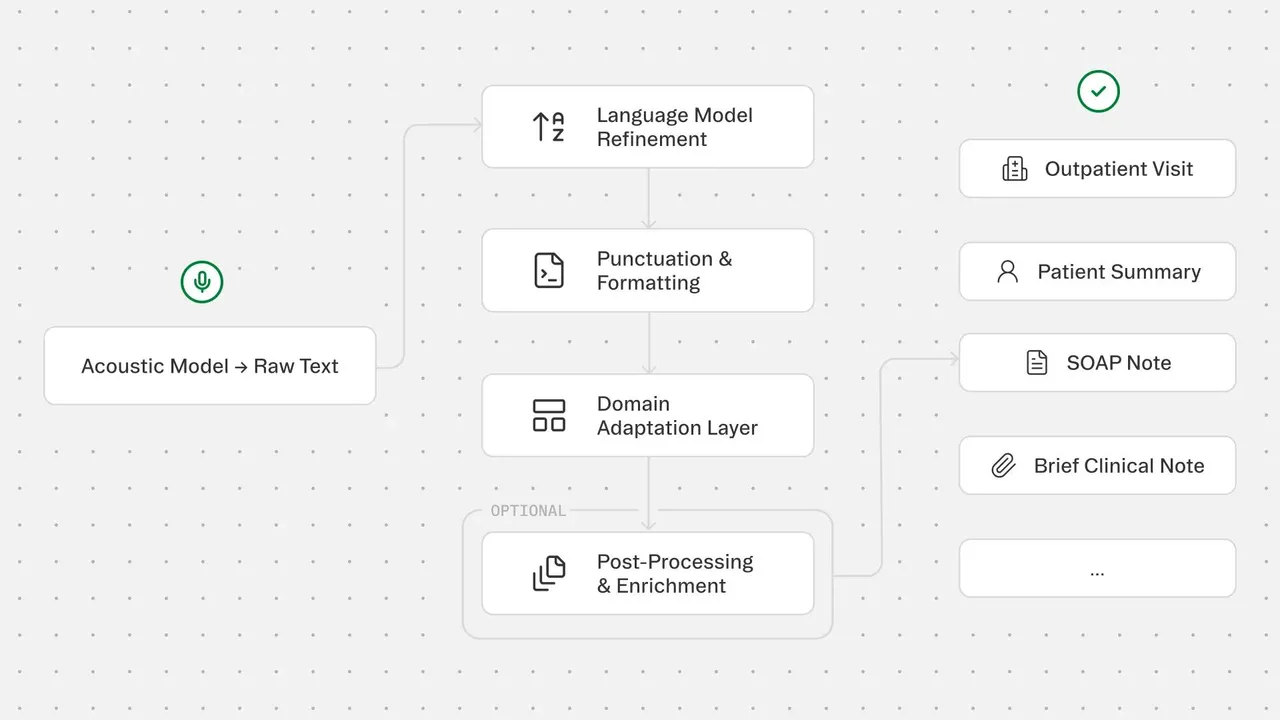
Symphony treats speech to text as a structured inference problem. Recognition, formatting, and correction run as an orchestrated pipeline rather than collapsing into one step. The result is text that is clinically accurate and operationally ready.
Stream in real time or upload batch
Stateless real-time dictation, stateful conversational transcription, and async batch processing all run through the same underlying model. Build across modes without managing separate vendors or accepting differences in accuracy.
Inject context, bias toward the keywords that matter
Supply a terminology list at inference time, and Symphony biases recognition toward the terms in your context - rare drug names, facility abbreviations, clinician identifiers. No fine-tuning, no retraining cycle. Reduces missed terms by ~50% without affecting precision.
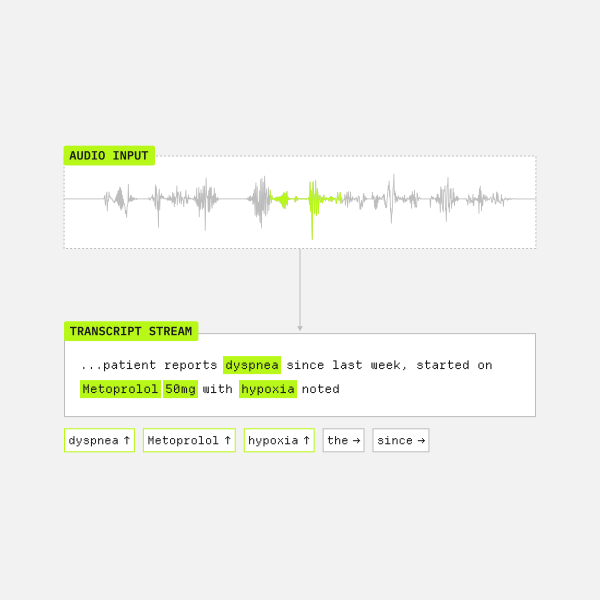
Catch quality problems before they reach the transcript
Symphony Audio Health Events surface real-time quality signals during the interaction, so your pipeline can prompt a correction rather than surface a bad transcript after the fact.
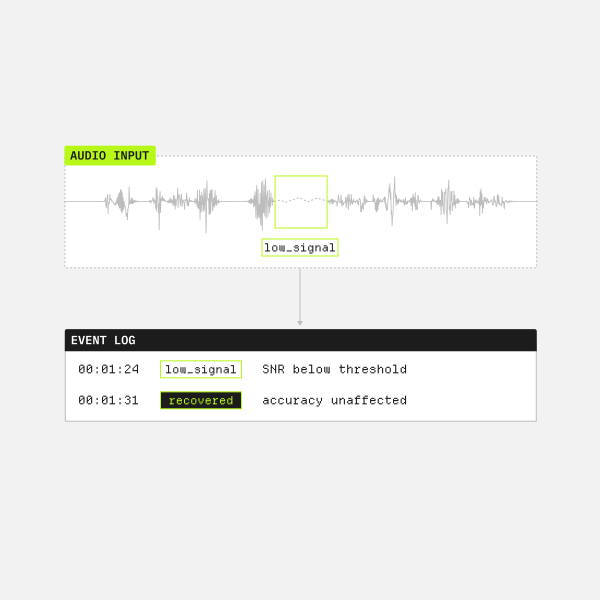
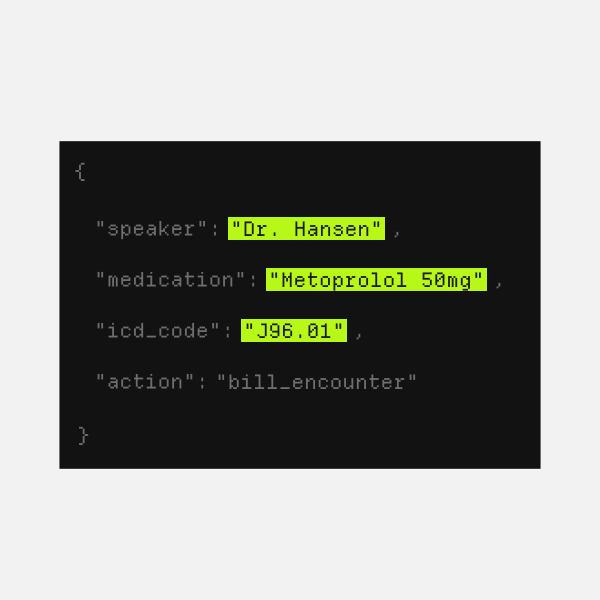
Structured outputs your agents can act on
Entities are structured, punctuation is rendered, dosages and units are in the right form. Your agents and downstream systems can act on the transcript without a post-processing layer.
Benchmarks
The most accurate speech-to-text for clinical use cases
Best-in-class performance across medical terminology, formatting, and dictation commands.
Word accuracy on clinical speech
1.4%
Word Error Rate. Outperforming ElevenLabs, OpenAI, AWS, NVIDIA, and Google by >20%, both in realtime and offline English benchmarks.
98%
Formatting accuracy. So dosages, units, dates, and measurements always render correctly for downstream use.
25%+
Improvement vs. legacy dictation. Symphony WER 4.1% vs. Dragon Medical One 5.7% WER on medical dictation benchmarks.
What builders say
“By adding Corti’s API directly into our platform, we’re giving customers the latest capabilities without forcing them to learn new systems or abandon familiar workflows.”
“In a clinical conversation, every word matters - a missed medication name, a misheard dosage, or a mistranscribed symptom can change the meaning of an encounter. Symphony’s accuracy on clinical terminology gives us the foundation to bring more trusted AI capabilities into clinical workflows with our Voicepoint Xenon® platform”
What’s included
- Read more
Commands
Control your application interface by voice, using spoken words to trigger actions and navigate fields.
 Read more
Formatting
Render dosages, units, dates, and measurements in clinical form automatically. No post-processing needed.
 Read more
Diarization
Attribute speech to the right speaker across multi-participant conversations.
 Read more
Interim results
Show transcript output in real time as the clinician speaks, word by word.
 Read more
Audio health events
Surface input quality signals in the API response, before a bad transcript reaches your users.
 Read more
Auto/spoken punctuation
Handle punctuation at the recognition layer for a natural dictation experience.
 Read more
Replacement rules
Control how words, phrases, and acronyms appear in final transcript output.
 Read more
Custom dictionary
Improve recognition for proper nouns, facility names, and specialty-specific terminology.
Production-ready
Global coverage across ~50 languages
One integration covers live streaming dictation, conversational transcription, and batch audio. No separate vendors. No accuracy tradeoffs between modes.
Build any voice-powered healthcare workflow
Symphony supports dictation, ambient documentation, and agentic workflows through a single API. No separate systems. No accuracy tradeoffs between modes.
Stream a conversation.
Receive a structured transcript.
Connect to /streams for stateful, real-time conversational transcription. Audio is associated with an ongoing interaction - diarization, contextual correction, and audio health events run natively in this mode.
- Speaker diarization segments the transcript by doctor and patient automatically
- Audio health events surface input quality issues in real time, before the encounter ends
- Get started with the Corti SDK in JavaScript and C# .NET
Low-latency transcription built for command-and-control.
Connect to /transcribe for stateless, real-time dictation. Built for command-and-control workflows where spoken commands control the interface, edit text, and trigger formatting operations.
- Industry-leading accuracy on medical dictation benchmarks, outperforming Dragon Medical One by 20%+
- Spoken punctuation, measurements, and abbreviations handled at the recognition layer
- Supply a keyterm list at inference time to bias recognition toward your vocabulary
Give your agents clean, structured input. Not raw text.
Symphony delivers structured, validated outputs your agents can act on directly. It handles the gap between what a clinician says and what your software needs to do.
- Structured outputs let voice directly drive workflows, orders, and documentation
- Context injection and controllable outputs mean your agent starts from verified input
- Controllable outputs reduce the surface area for LLM hallucination downstream
| Feature | Symphony | Generic ASR | Legacy dictation |
|---|---|---|---|
| Clinical intelligence | |||
| Medical term accuracy | YesBest-in-class | No | No |
| Real-time formatting | YesNative | No | No |
| Spoken punctuation | YesNative | No | No |
| Custom commands | YesNative | No | No |
| Speaker diarization | YesNative | Partial | Partial |
| Audio health events | YesNative | No | No |
| Developer experience | |||
| Flexible developer API | Yes | No | No |
| Embeddable in your app | Yes | No | No |
| Structured outputs | YesAgent-ready | No | Cursor input |
Read the research behind Symphony for Speech-to-Text
Nine years of peer-reviewed research, published at NeurIPS, ICML, ICLR, and ACL. Now shipping as an API.
Start building with Symphony for Speech-to-Text
$50 free credits. Full API access. No card required.
Symphony is top-ranked on medical dictation benchmarks across English, French, and German, and is available across 14 languages worldwide. It outperforms OpenAI, ElevenLabs, Whisper, and Parakeet on clinical audio, and matches or exceeds state-of-the-art on general-purpose benchmarks.
$0.0065 per audio minute, all inclusive. Diarization, contextual correction, keyterm biasing, audio health events, multichannel speaker attribution, and all supported languages are included at no extra cost. No separate charges for transcript output. 10 minutes = $0.07. 1 hour = $0.39.
Yes. Symphony is built for healthcare environments, with sovereign cloud deployment options for organizations with strict data residency requirements.
Symphony is stress-tested on non-speech audio and aggressively segmented inputs. It reports lower spurious insertion rates than every major competing system - an important signal for production clinical deployments.
/transcribe is a stateless WebSocket endpoint for real-time dictation and voice-controlled interfaces. /streams is a stateful WebSocket endpoint for conversational transcription, where audio is associated with an ongoing interaction. /transcripts is an async REST endpoint for batch processing of pre-recorded audio files. All three share the same underlying pipeline with no performance differences between modes.
On MedDictate, a realistic English medical dictation benchmark, Symphony achieves 4.6% WER, compared to 5.7% for Dragon Medical One, with higher medical term recall and a lower false discovery rate (0.79% vs. 1.33%). Unlike front-end dictation applications, Symphony is an API built for developers - no client-side software, no vendor lock-in, and structured outputs that downstream systems can act on directly.
Every developer gets $50 of API credits to start - enough to process nearly 8,000 minutes of audio. Get an API key, run your own audio through the appropriate endpoint, and measure results against a gold standard transcript using Corti Canal, our open-source evaluation tool that reports Word Error Rate, Character Error Rate, and Medical Term Recall. If you want help setting up a benchmark or interpreting results, reach out to help@corti.ai.